Hello Atlassian Community,
We are investigating a severe and unexpected issue with Jira Cloud webhook delivery that began on Monday, April 20, 2026.
Our application depends on Jira webhooks to receive ticket updates from boards in our internal system. Before that date, webhook callbacks were delivered almost instantly and consistently. Starting April 20, delivery dropped dramatically, in some cases to nearly zero. We now receive only an occasional webhook over a long period of time, even though the webhooks were successfully created and the callback URL is reachable.
We are using the official Jira Cloud webhook APIs, including:
- Get dynamic webhooks for app
- Register dynamic webhooks
- Delete webhooks by ID
- Extend webhook life
Relevant documentation:
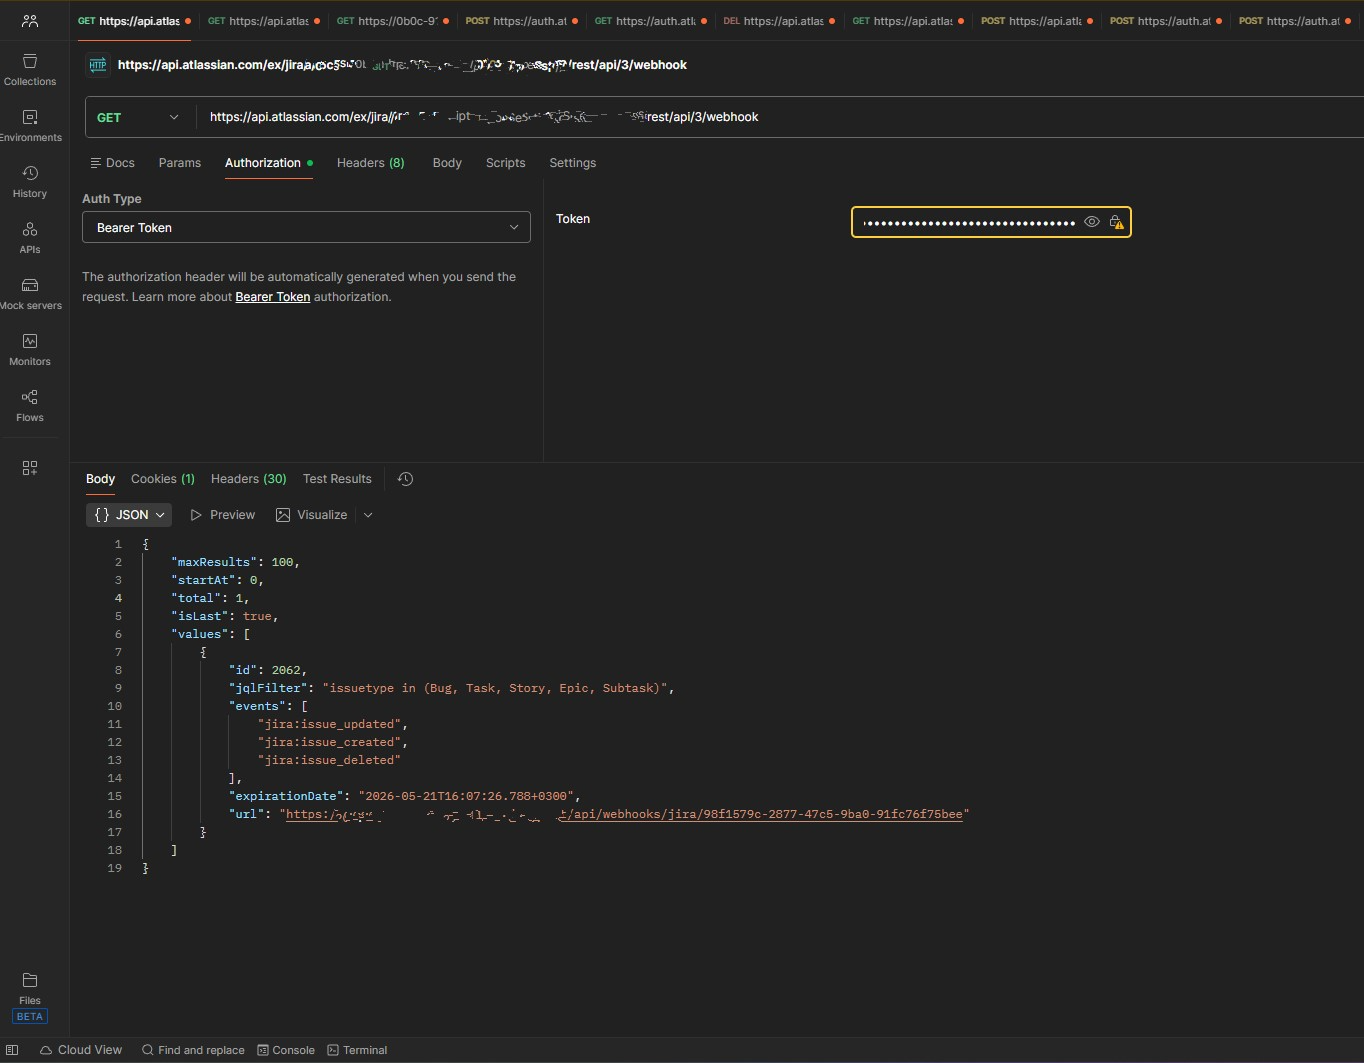
We also attached a screenshot showing the webhook is present and properly configured.
What we have already verified
No configuration was changed on our side when the issue started. We also verified that:
- the webhook was created successfully through the REST API,
- it is present and active,
- the configured events and JQL filters match what we intended,
- the callback endpoint is publicly reachable,
- our service is returning successful responses for incoming requests,
- we are not using deprecated REST API behavior for webhooks,
- the experimental Get failed webhooks endpoint returned no failed webhook data (used manually in Postman to validate whether any webhook-related errors could take place),
- Atlassian status pages showed Jira and related products as operational, with no webhook-related incident reported.
Common questions we checked in advance
Registration and quota restrictions
According to Atlassian documentation, OAuth 2.0 apps have webhook limits, and legacy Connect apps have different limits. In our case, this does not appear to be the issue because we use only one webhook per board/user context, and we are not approaching any quota boundary. We also tested both older long-lived webhooks and freshly created ones, and the issue reproduces in both cases.
Network and URL constraints
Our callback endpoint is public, uses HTTPS, and is reachable. Since some webhook requests still do arrive, this does not look like a certificate, firewall, redirect, or port-related problem.
JQL filtering constraints
We are following the supported JQL filtering recommendations and are not relying on unsupported filtering behavior. We do not believe JQL filtering is the cause of the missing deliveries.
Concurrency and throughput limits
Our usage is very light. We generally receive only one request per change, and our handler responds in under a few seconds. We are far below any expected concurrency or throughput limit.
Retry policy
We are not seeing signs of failed delivery or retry behavior on our side. The endpoint is reachable and responding, so this does not look like a retry-loop or timeout issue.
Observed behavior
The key symptom is that webhook delivery suddenly became extremely sparse starting April 20, 2026. Some events still appear, but the majority do not. From our perspective, this looks like deliveries are being skipped or not sent at all, rather than simply delayed.
Questions for the community
Has anyone else seen a similar drop in Jira Cloud webhook delivery starting around April 20, 2026?
Could this be related to any backend change, delivery issue, or undocumented behavior on Atlassian’s side?
Are there any additional diagnostics we should check to determine whether events are being dropped before delivery?
Any guidance would be greatly appreciated.


