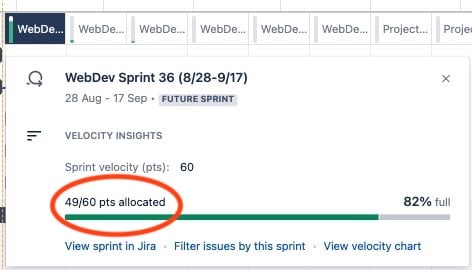
Hello, all.
We are using Advanced Roadmaps for Jira v9.12.11 (Jira server v9.12.11). We have a scrum board that is the data source for an Advanced Roadmap Plan, and the team has sprints that are managed via that scrum board. As such, we are able to view the sprints across the top of the plan.
The problem we are seeing is the calculation of capacity for each sprint. Different people can look at the same exact plan, and the number is different. I can add a filter tht should reduce the number, and it grows. Removing the filter gives it a third value.
While it is sometimes correct (particularly for future sprints that aren't fully planned), most of the time the value reported is much higher than the number of story points on the tickets that are included in the sprint. I can't seem to figure out any rational correlation to the issues (stories, bugs, tasks and epics are all we use).
I have looked at the story points assigned at the Epic level (which we use for high-level estimation before breaking down the work into individual issues), the Target Start and End dates, the sprints that are assigned (or not assigned) and I just can't find the pattern.
Could somebody explain how this number is calculated?
Thanks,
Matt
P.S. Attaching a photo of the display/field I'm talking about here: