Hi,
I am working on the ability to import a CSV file into JIRA. The file contains a set of issues that could be represented with Stories, Epics and Sub-Tasks/Tasks.
My goals are:
1) to create the set of issues into JIRA maintaining the issue types as defined in the CSV file,
2) to keep the relationships between the different issue types contained in the file:
- relationship between any issue type and epic
- relationship between n sub-tasks and their story parent
Could you please help me to understand how the file should be configured in order to keep those relationships listed above? Please see how my CSV file looks in order to confirm if this is the expected format: 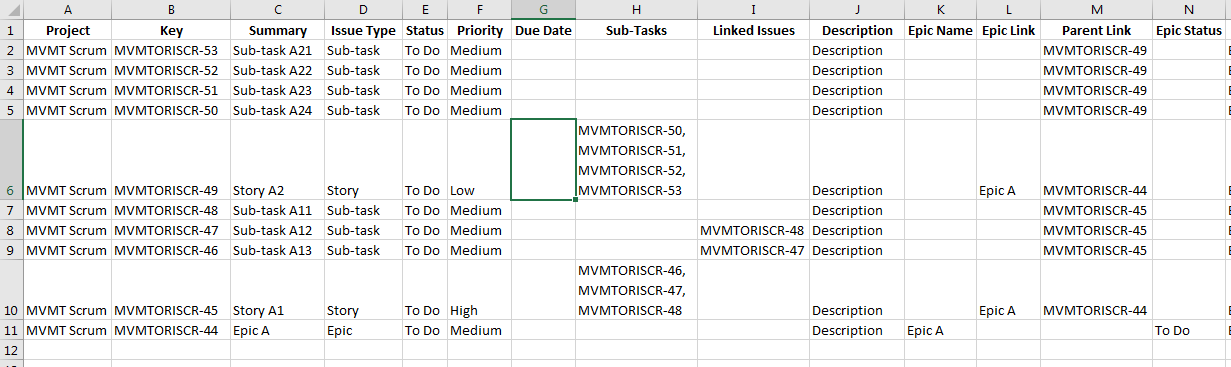
And this is configuration of file used to map the fields:
{
"config.version" : "2.0",
"config.project.from.csv" : "false",
"config.encoding" : "UTF-8",
"config.email.suffix" : "@",
"config.field.mappings" : {
"Issue Type" : {
"jira.field" : "issuetype"
},
"Sub-Tasks" : {
"jira.field" : "issuetype"
},
"Parent Link" : {
"jira.field" : "subtask-parent-id"
},
"Description" : {
"jira.field" : "description"
},
"Linked Issues" : {
"link.type" : "10000"
},
"Summary" : {
"jira.field" : "summary"
},
"Epic Name" : {
"existing.custom.field" : "10005"
},
"Key" : {
"jira.field" : "issue-id"
},
"Epic Link" : {
"existing.custom.field" : "10006"
}
},
"config.value.mappings" : {
},
"config.delimiter" : ",",
"config.project" : {
"project.type" : null,
"project.key" : "MVMTORISCR",
"project.description" : null,
"project.url" : null,
"project.name" : "MVMT Scrum",
"project.lead" : "mvmtori@ar.ibm.com"
},
"config.date.format" : "dd/MMM/yy h:mm a"
}
In addition, why should I use Tasks instead of Sub-Tasks in order to establish the "parent Story > children Sub-Tasks/Tasks" relationship? I tried with both Task and Sub-Task issue types but the parent-children relationship only worked with Sub-Tasks.
Look forward to any assistance.
Thanks in advance,
Victoria.


