In this guide, we will walk through how to import worker data from Rippling into Assets. We will cover authentication, the Get Workers API, field mapping, and setting up scheduled imports.
Step 1: Authenticate to the Rippling API
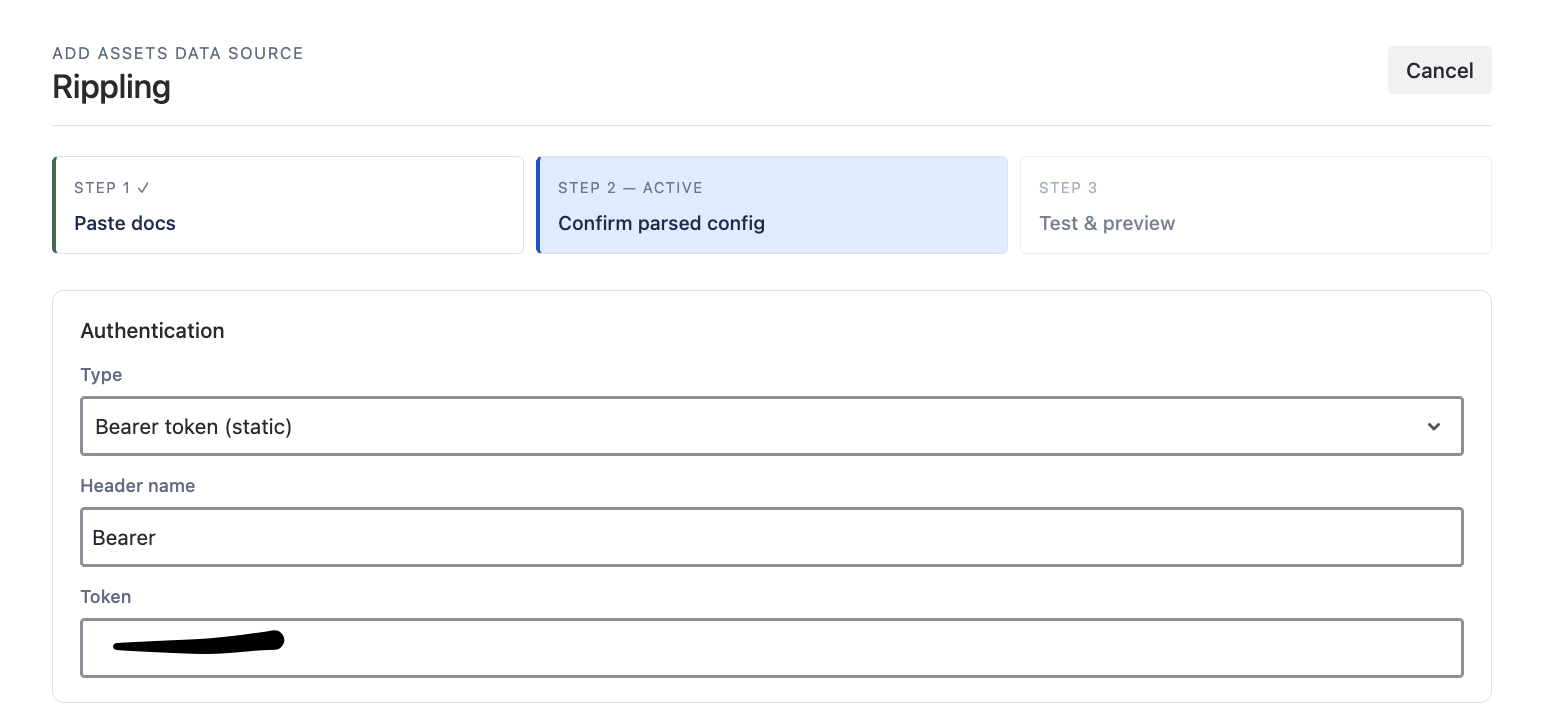
Rippling's REST API uses bearer token authentication. Every request must include the header:
<span>Authorization: Bearer <YOUR_API_TOKEN></span>
To generate a token, follow the steps in Rippling's API Tokens documentation:
- In Rippling, navigate to the API Tokens app (search for it, or find it under Settings).
- Click to create a new API token, provide a name and unique identifier, and select the API version.
- Configure the scopes for the token (see below).
- Copy and securely store the token.
Use the token generated above in the OnLink connection.
Permissions needed to read worker data
This is the part people most often get wrong, so let's highlight it. Rippling scopes follow the {resource_name}.{read|write} convention, and two rules apply:
- Tokens inherit the permissions of the user who creates them. You can only grant scopes that your own permission profile allows, so create the token as an admin with access to worker data.
- Grant least privilege. For a read-only import into Assets, you only need read scopes.
For this integration, enable read access to worker data:
| Scope |
Why it's needed |
|---|
workers.read |
Required to call the /workers endpoint |
users.read |
(Optional) If you expand or look up the associated user record |
departments.read |
(Optional) If you expand department details instead of just IDs |
teams.read |
(Optional) If you expand team details instead of just IDs |
employment-types.read |
(Optional) If you expand employment type details |
If your API calls return a 403, check both the token's scopes and the permission profile of the user who created the token.Make sure you have read access to only the objects you want to import to Assets.
Step 2: Get Workers from the Rippling API
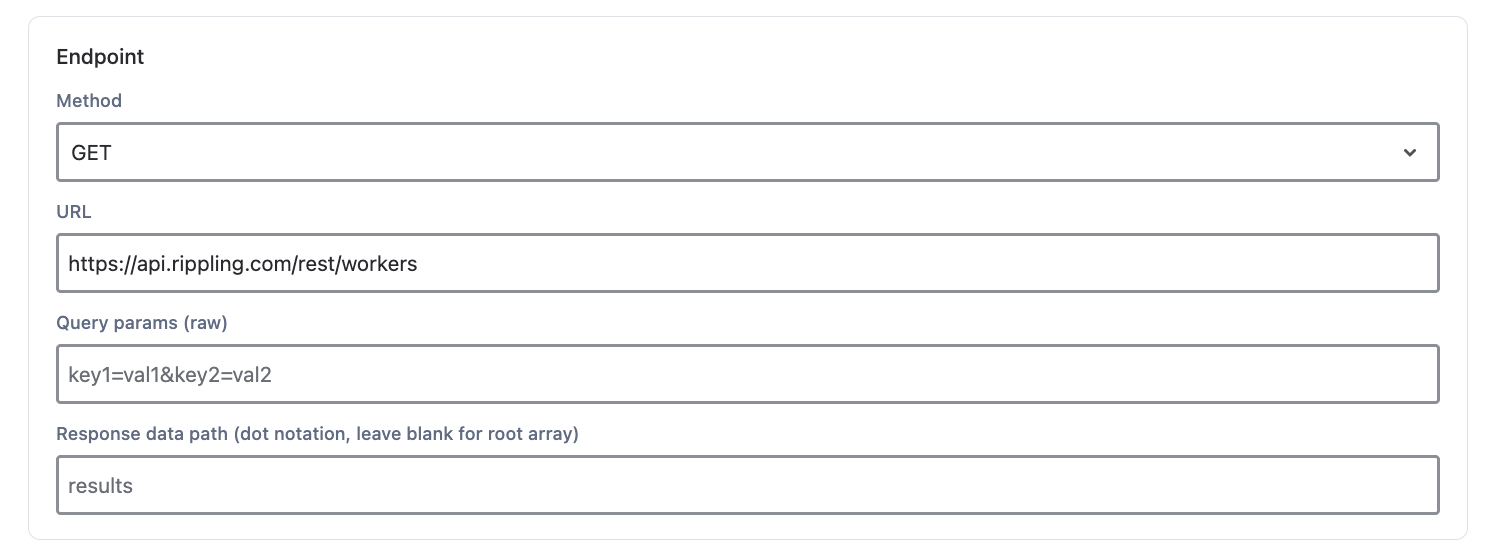
Worker data comes from the List Workers endpoint:
<span>GET https://rest.ripplingapis.com/workers</span>
A worker represents a person's HR worker profile (employment/engagement) in your company. A quick test with curl:
bash
<span>curl --request GET \
</span><span>  --url "https://rest.ripplingapis.com/workers" \
</span><span>  --header "Authorization: Bearer <YOUR_API_TOKEN>"</span>
Configuring in OnLink
Filters
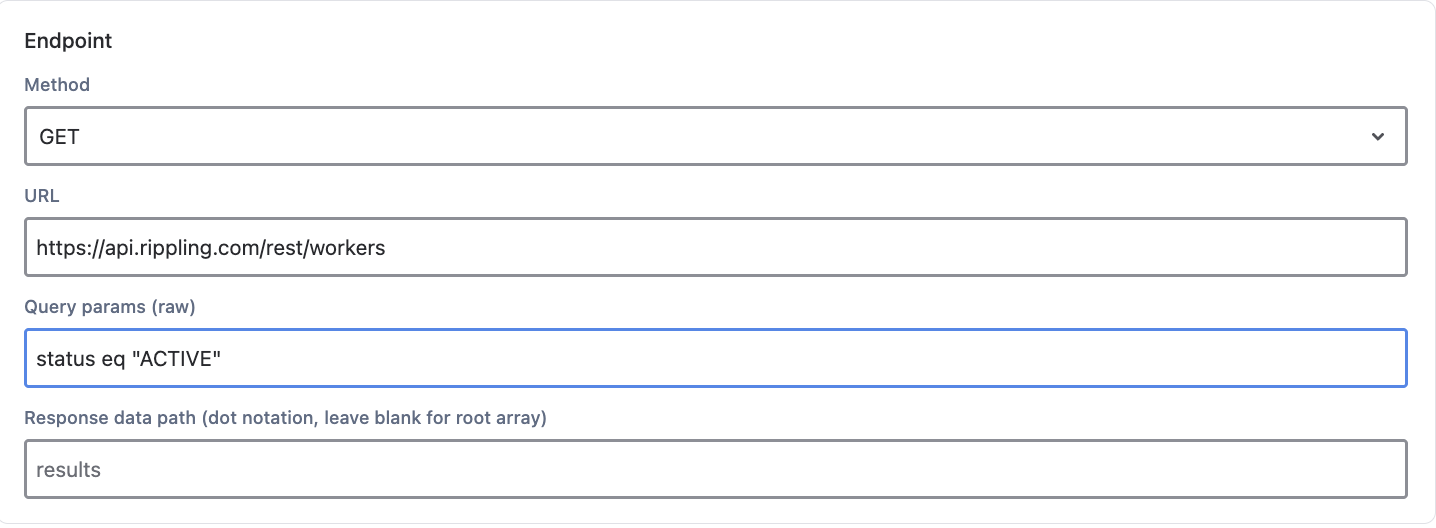
You can refine results using the filter query parameter. Filterable fields include status, work_email, user_id, created_at, and updated_at. For example, to import only active workers:
<span>GET /workers?filter=status eq "ACTIVE"</span>
Filtering at the source keeps terminated workers (or test records) out of your Assets schema entirely — a much cleaner approach than importing everything and cleaning up afterward.
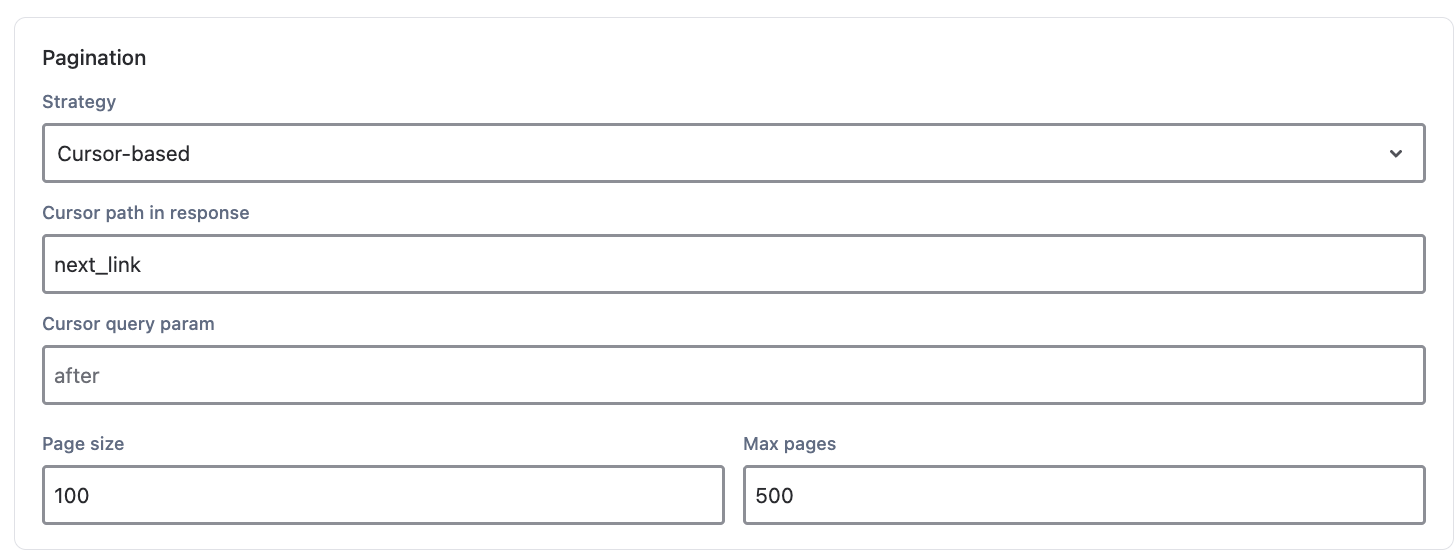
Pagination
The endpoint returns a paginated list using cursor-based pagination:
- Use the
limit parameter to control page size.
- Each response includes a
next_link / cursor for the next page; keep following it until it returns null.
Step 3: Configure the OnLink Mapping
Before mapping, make sure your Assets schema is ready:
- In JSM, go to Assets → your schema → Schema configuration → Import → Create Import → select OnLink Importer, give it a name, and create it.
- Click the three dots → Configure app, set a name in the popup, and save.
- Open the OnLink app (via "Manage your apps" in Jira), find the new configuration, select Edit, and choose Rippling as the source system with your API token from Step 1.
Tip: Create your Worker object type and its attributes in Assets first. The attribute names on the right side of the mapping must match your Assets attribute names exactly.
Sample mapping
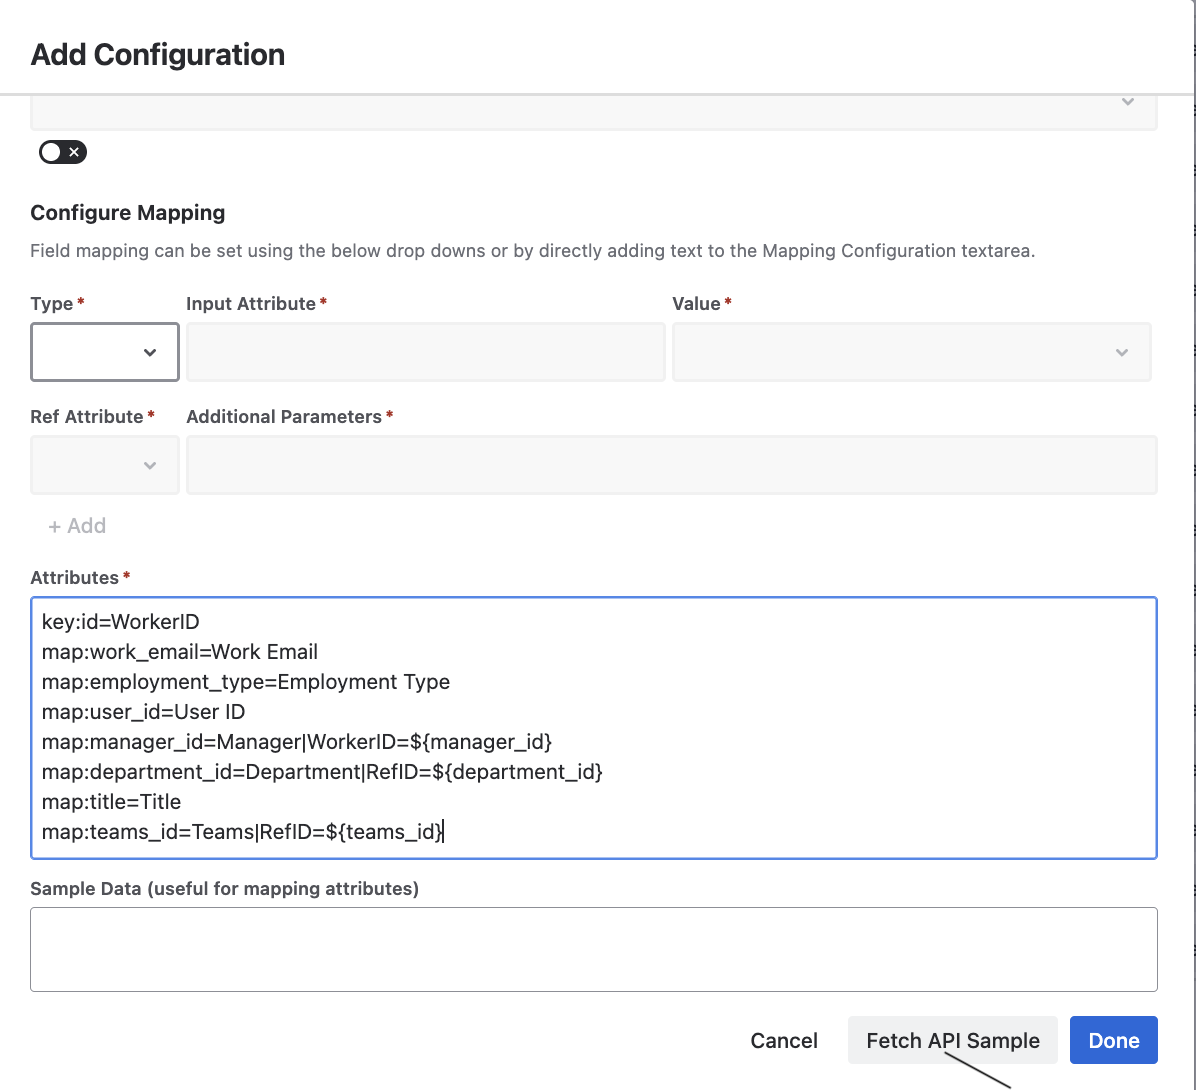
Here is a sample OnLink mapping for the Rippling worker fields:
<span>key:id=WorkerID
</span><span>map:work_email=Work Email
</span><span>map:employment_type=Employment Type
</span><span>map:user_id=User ID
</span><span>map:manager_id=Manager|WorkerID=${manager_id}
</span><span>map:department_id=Department|RefID=${department_id}
</span><span>map:title=Title
</span><span>map:teams_id=Teams|RefID=${teams_id}</span>
Understanding the mapping syntax
| Line |
Description |
|---|
key:id=WorkerID |
The key prefix defines the unique identifier. Rippling's worker id maps to the WorkerID attribute in Assets, so future syncs update existing objects instead of creating duplicates. |
map:work_email=Work Email |
The map prefix connects a source field to an Assets attribute. Syntax: map:[Rippling_Field]=[Assets_Attribute]. |
map:title=Title |
Simple text mapping for the worker's job title. |
map:employment_type=Employment Type |
Captures whether the worker is a full-time employee, part-time, or contractor — useful for access policies and automations. |
map:manager_id=Manager|WorkerID=${manager_id} |
Reference mapping. Everything after the pipe is an AQL lookup: Manager is an Assets attribute that points to another Worker object, and ${manager_id} is matched against that object's WorkerID. This builds the org hierarchy inside Assets. |
map:department_id=Department|RefID=${department_id} |
Same pattern for departments — links the worker to a Department object whose RefID matches. If the referenced object doesn't exist, OnLink can create it (config:enable_object_creation=true), or you can suppress that with |create=false. |
map:teams_id=Teams|RefID=${teams_id} |
teams_id is an array — a worker can belong to multiple teams. OnLink maps each element to a referenced Team object, giving the attribute cardinality > 1 in Assets. |
Step 4: Fetch a Sample Record
Before running a full import, use the Fetch Sample button in the OnLink configuration screen. This calls the Rippling API with your token and returns one raw JSON worker record — which does three things for you:
- Verifies authentication — if your token or scopes are wrong, you'll find out now, not mid-import.
- Shows you the exact field names available for mapping, including any custom fields your Rippling admin has configured.
- Lets you validate your mapping against real data instead of guessing.
A sample worker record looks like this:
json
<span>{
</span><span>  "id": "worker_8f2b1c",
</span><span>  "user_id": "user_3d9a7e",
</span><span>  "work_email": "alex.rivera@acme.com",
</span><span>  "title": "Senior Platform Engineer",
</span><span>  "employment_type": "FULL_TIME",
</span><span>  "manager_id": "worker_5c4e2a",
</span><span>  "department_id": "dept_1a2b3c",
</span><span>  "teams_id": ["team_9x8y7z", "team_4q5r6s"],
</span><span>  "status": "ACTIVE",
</span><span>  "start_date": "2023-04-17",
</span><span>  "created_at": "2023-04-10T08:15:30Z",
</span><span>  "updated_at": "2026-06-30T12:01:44Z"
</span><span>}</span>
Manual Import First, Then Schedule
OnLink processes data in two steps Get Data and Import Data:
- Get Data: Click Get Data in OnLink. This fetches workers from Rippling (handling pagination across all pages). Watch the Job Logs until you see: "No more pending records. Data will be imported on next Import run."
- Import: Once Get Data completes, click Import. OnLink pushes the fetched records into your Assets schema, creating new Worker objects and updating existing ones based on your
key field.
- Verify: Open your Assets schema and spot-check the imported objects. Confirm the attribute values look right, manager and department references resolved correctly, and the object count matches your expected active worker count in Rippling.
- Schedule: Once you're happy with the data, enable the sync schedule in OnLink. Production runs are fully automated on the cadence you choose hourly, daily, or a custom interval.
Frequently Asked Questions (FAQ)
What is the best unique identifier for Rippling imports?
The worker id from Rippling. Map it with key:id=WorkerID so OnLink updates existing objects on every sync instead of creating duplicates.
Can I import only active workers?
Yes. Filter on the status field so terminated workers never enter your Assets schema, or import all workers and map status to an attribute if you want visibility into offboarded workers too.
My API calls return 403?
Two things to check: the token's scopes must include workers.read, and the Rippling user who created the token must themselves have permission to view worker data — tokens inherit the creator's permissions.
How do I map manager and department as object references instead of plain text?
Use the pipe syntax: map:manager_id=Manager|WorkerID=${manager_id}. The AQL after the pipe tells OnLink how to look up the referenced object in your schema.
Does OnLink support automatic synchronization?
Yes. Use manual Get Data + Import runs for testing, then define a schedule for production so JSM Assets stays synchronized with Rippling automatically.
Ready to import your Rippling data to Assets?
👉 Try OnLink on the Atlassian Marketplace today
References:
