Using Confluence 7.19.6
I am building a dashboard page to combine Jira metrics for completed, incomplete and changed stories from multiple engagement teams. Each team creates a page using Jira Sprint Report data pasted into tables. Table Transformer is used to merge those tables, and a Pivot table is created to summary counts of stories and story points (see images).

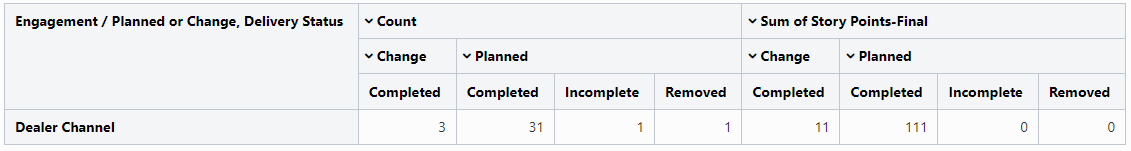
Table Excerpt Include is used in the Dashboard page to pull in multiple pivots like above, nested in a Table Transformer to generate final table for metrics reporting.
If the Pivot table fields are consistent, this works perfectly. However, the Pivot columns vary because some teams may not have incomplete or removed stories, for example, or have changed stories, like in the 2nd table above.
Table Excerpt Include cannot summarize all these pivots into a single report table due to the Pivot field inconsistency, and so Table Transformer cannot identify fields properly.
I added dummy items to the individual engagement pages, and that works in making the layouts consistent. However, the dummy items are picked up as actual records, so the counts are wrong.
Is there a way to use Table Transformer with Table Excerpt Include to create "dummy" columns where real data is missing? For example, using the table samples above, I'd need the first table to have an empty "Change / Completed" column for Stories and one for Story Points to align with the second table.


