I'm currently working on a project where this is the ask -
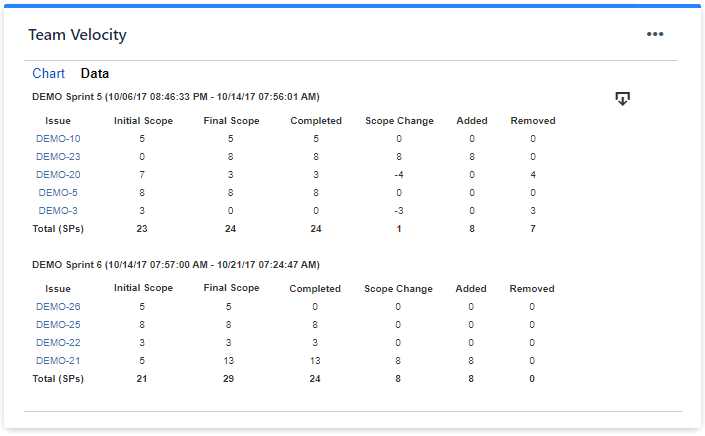
At the end of the sprint, run a script to fetch separate lists of issues (and their story points) that
- were committed to the sprint at the start of the sprint.
- were not committed to the sprint at the start of the sprint, but added later.
- completed during the sprint.
- were removed from the sprint during the sprint.
- are not complete at the end of sprint.
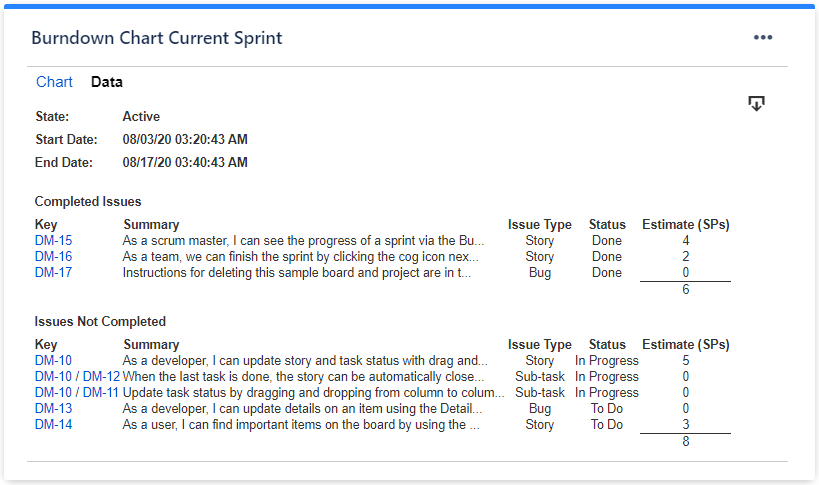
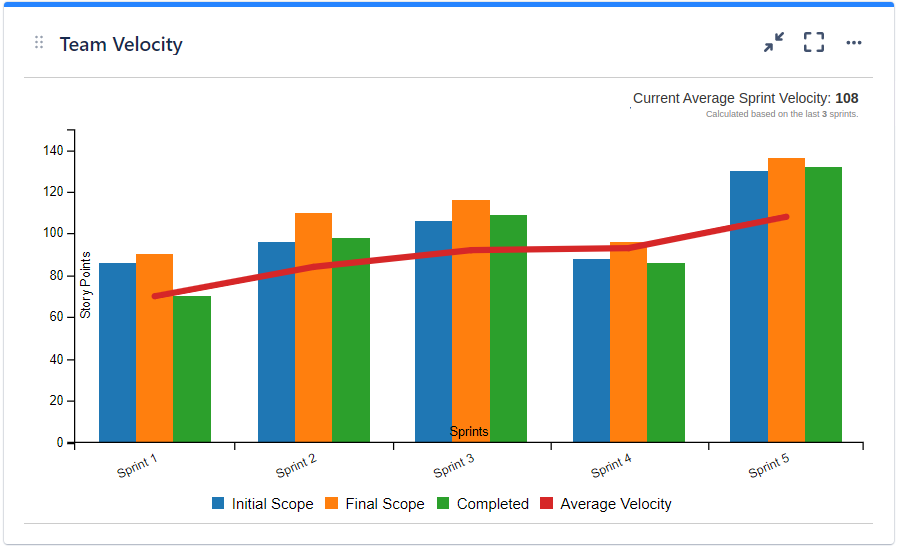
I see all these data are already present in the burndown chart in Jira. But I didn't find any way to export that data in an excel or csv or anything.
I then tried doing it via REST API calls, but apparently there's no direct endpoint for burndown chart. I can fetch the last sprint's sprintID by parsing the output of this endpoint -
https://$domain.atlassian.net/rest/agile/1.0/board/$boardId/sprint
and once I have correct sprintID, I can use that to fetch issues in that sprint via this -
https://$domain.atlassian.net/rest/agile/1.0/sprint/{sprintId}/issueBut that would be the "current" list of issues in that sprint (e.g. when the sprint has ended). I did not find any way to get list of issues when the sprint had started.
One option would be running the script at the start of the sprint, saving the output in some txt file. And then running the script again at the end of the sprint, saving the output in some txt file and comparing the two.
Problem with this is:
The manager (end-user of the script) will have to remember to run the script at the start of the sprint, and then remember to save the file somewhere he'll remember etc. That's not a good user experience for him. Ideally, he should be able to just run the script once and get the details for the last closed sprint.
So, that's where I'm stuck. Any tips on how to approach / solve this?